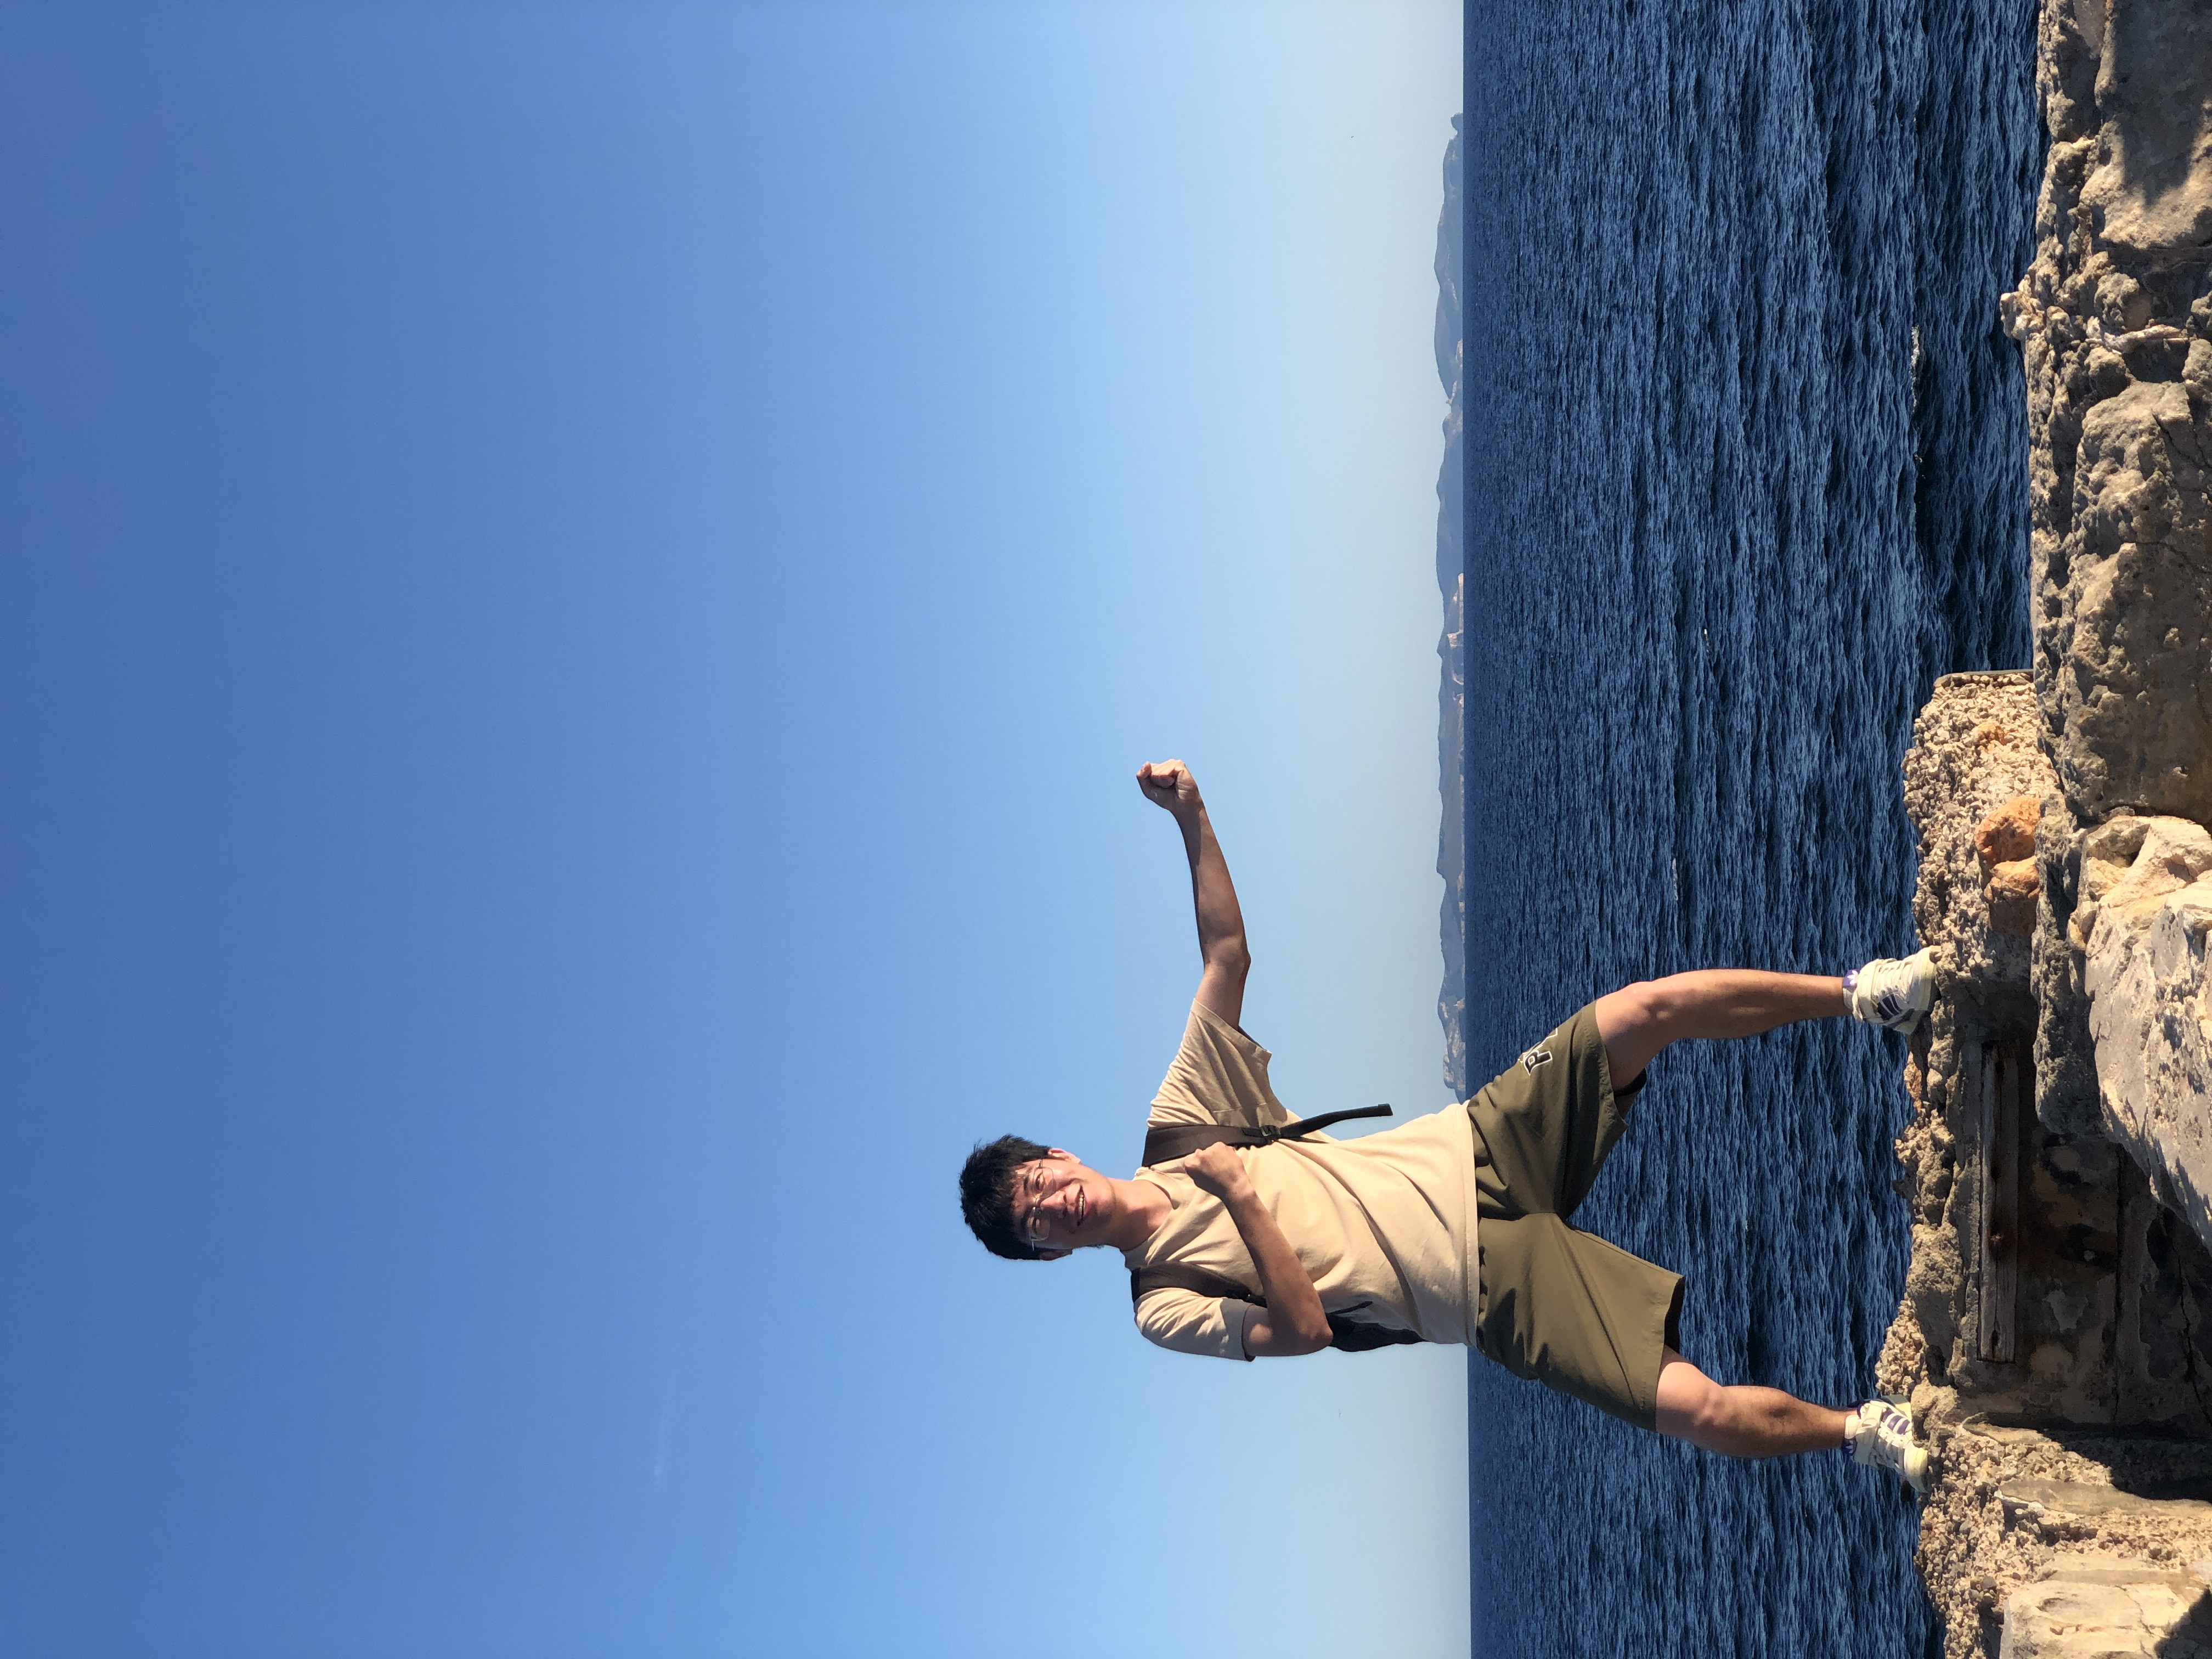
I am a Ph.D. student at Technical University of Munich, majoring in computer science and supervised by Prof. Dr. Gjergji Kasneci. Prior to that,I recieved both my bachelor and master from Tsinghua University, majoring in Artificial Intelligence.
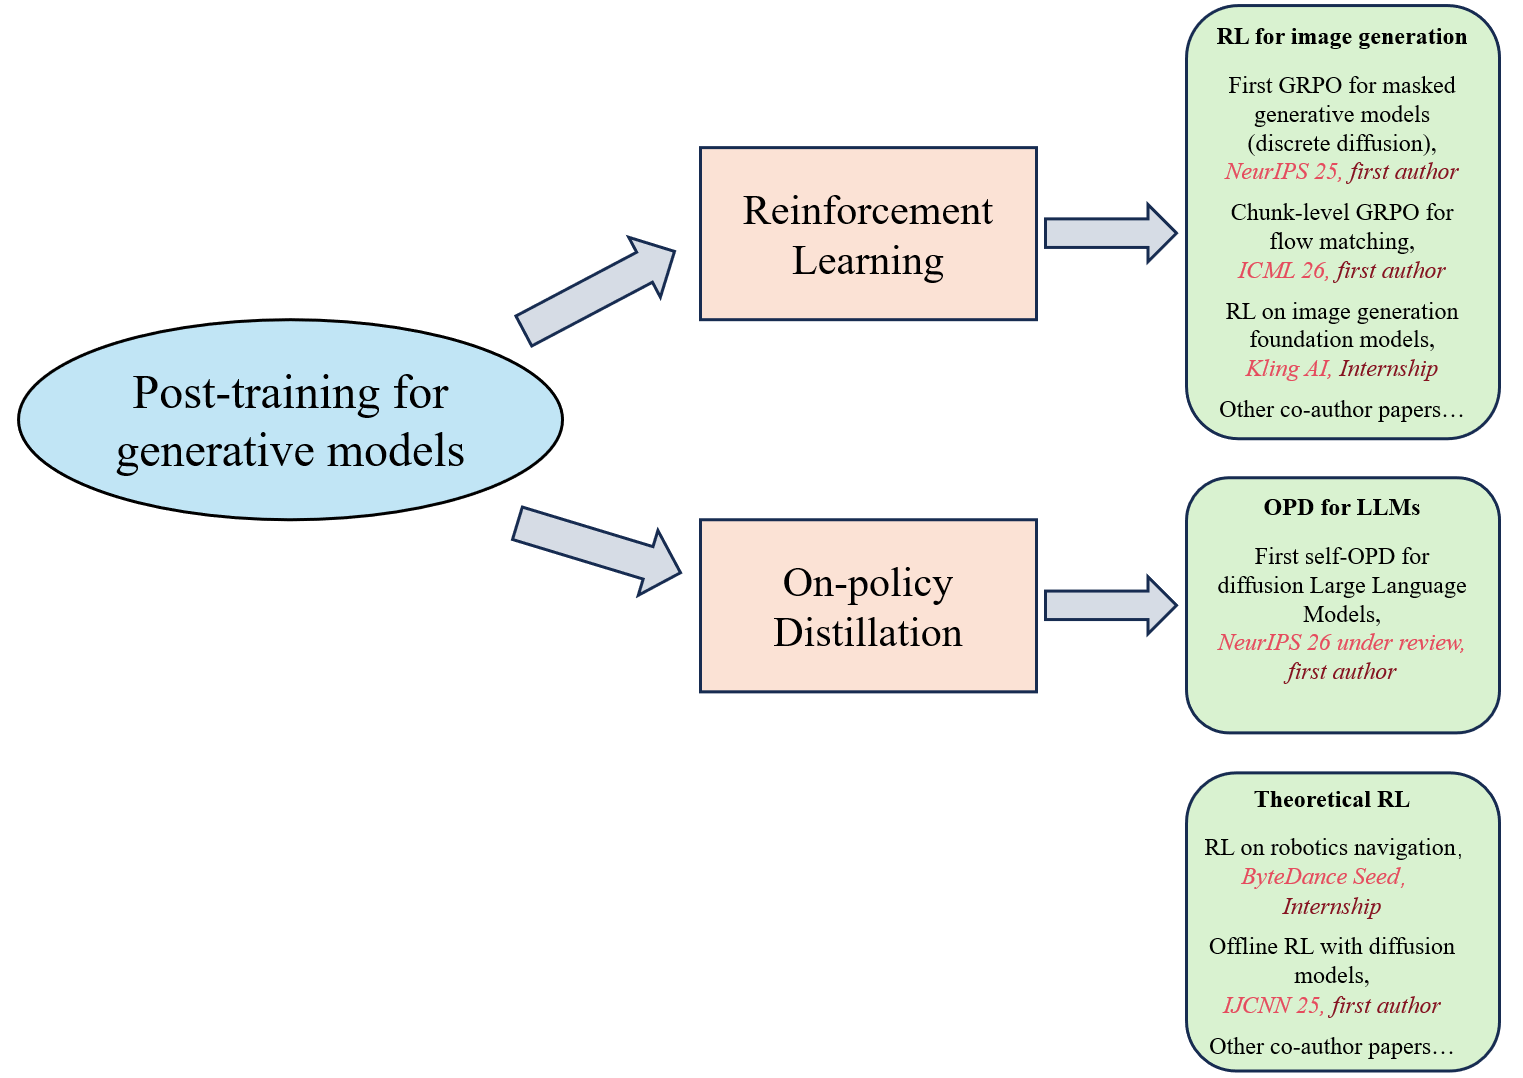
My research interests focus on the post-training paradigm (mainly as RL and OPD), for both LLMs and diffusion models. I have several top-tier publications as well as frontier lab internship experiences in this area.
I am always actively looking for research internship opportunities. Feel free to reach out to me if there is a match!
I am also opened to collaboration, especially (1) if you can give me SSH access to a large GPU cluster, or (2) if you are seeking for some hands-on guidance. If you are interested, please drop me an email. I check it every day!
 Curriculum Vitae
Warning
Problem: The current name of your GitHub Pages repository ("Solution: Please consider renaming the repository to "
http://".
However, if the current repository name is intended, you can ignore this message by removing "{% include widgets/debug_repo_name.html %}" in index.html.
Action required
Problem: The current root path of this site is "baseurl ("_config.yml.
Solution: Please set the
baseurl in _config.yml to "Education
-
 Technical University of Munich2026 - 2029
-
 Tsinghua University2023 - 2026
-
Tsinghua UniversityBachelor
Electronic Engineering2018 - 2022
Experience
-
Jan. 2026 - May. 2026
-
Jul. 2025 - Oct. 2025
-
Research Intern
Supervised by Dr. Yansheng Wang
Worked on robotics decision-making from video generationMarch. 2025 - Jul. 2025 -
Research Intern
Worked on autonomous drivingJune. 2021 - Aug. 2021
Honors & Awards
-
Outstanding Graduates, Tsinghua University2026
-
First Class Outstanding Student, Tsinghua University2025
News
Selected Publications (view all )
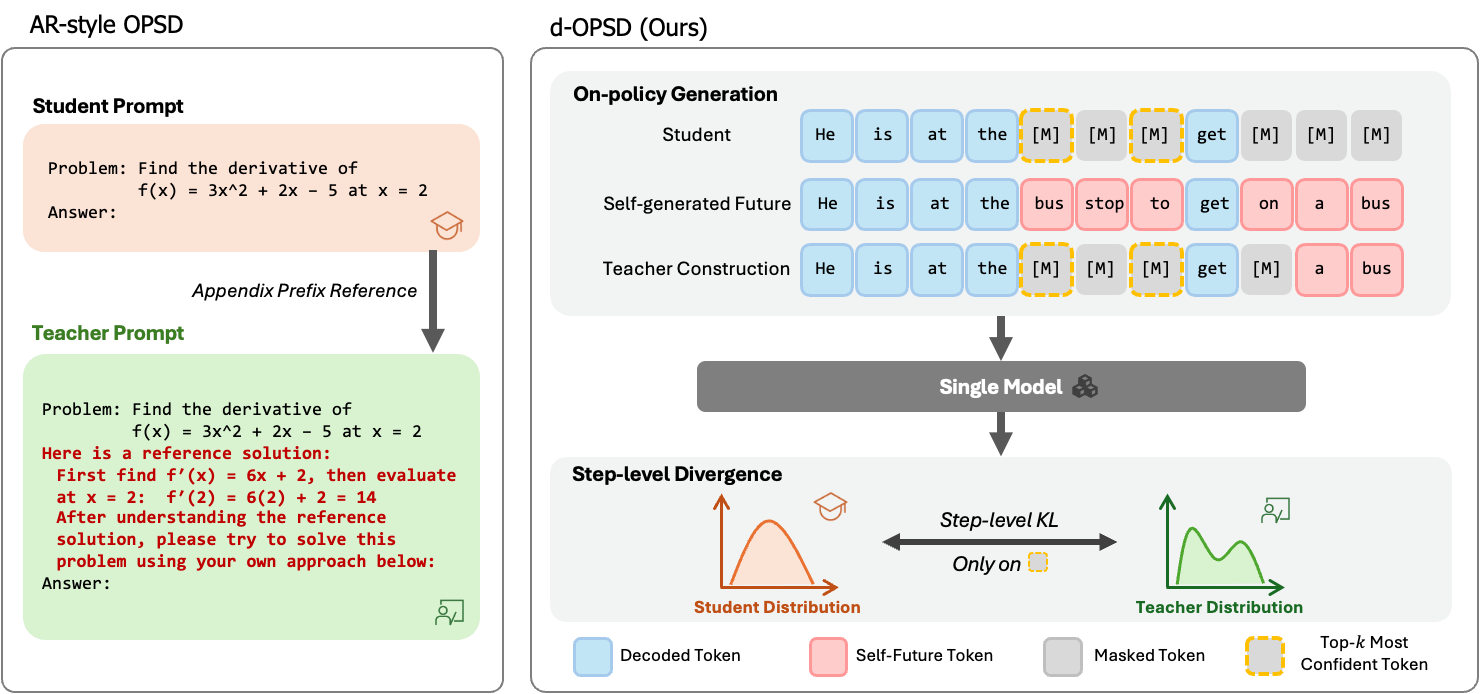
Learning from the Self-future: On-policy Self-distillation for dLLMs
Yifu Luo*, Zeyu Chen*, Haoyu Wang, Xinhao Hu, Yuxuan Zhang, Zhizhou Sha, Shiwei Liu (* equal contribution)
Preprint 2026
Propose the first OPSD approach for dLLMs. We reframe the OPSD formulation from prefix conditioning to the selfsuffix generation conditioning tailored specifically for dLLMs. We also shift dense supervision from the token-level to steplevel, aligning training with the iterative denoising nature of dLLMs.
Learning from the Self-future: On-policy Self-distillation for dLLMs
Yifu Luo*, Zeyu Chen*, Haoyu Wang, Xinhao Hu, Yuxuan Zhang, Zhizhou Sha, Shiwei Liu (* equal contribution)
Preprint 2026
Propose the first OPSD approach for dLLMs. We reframe the OPSD formulation from prefix conditioning to the selfsuffix generation conditioning tailored specifically for dLLMs. We also shift dense supervision from the token-level to steplevel, aligning training with the iterative denoising nature of dLLMs.
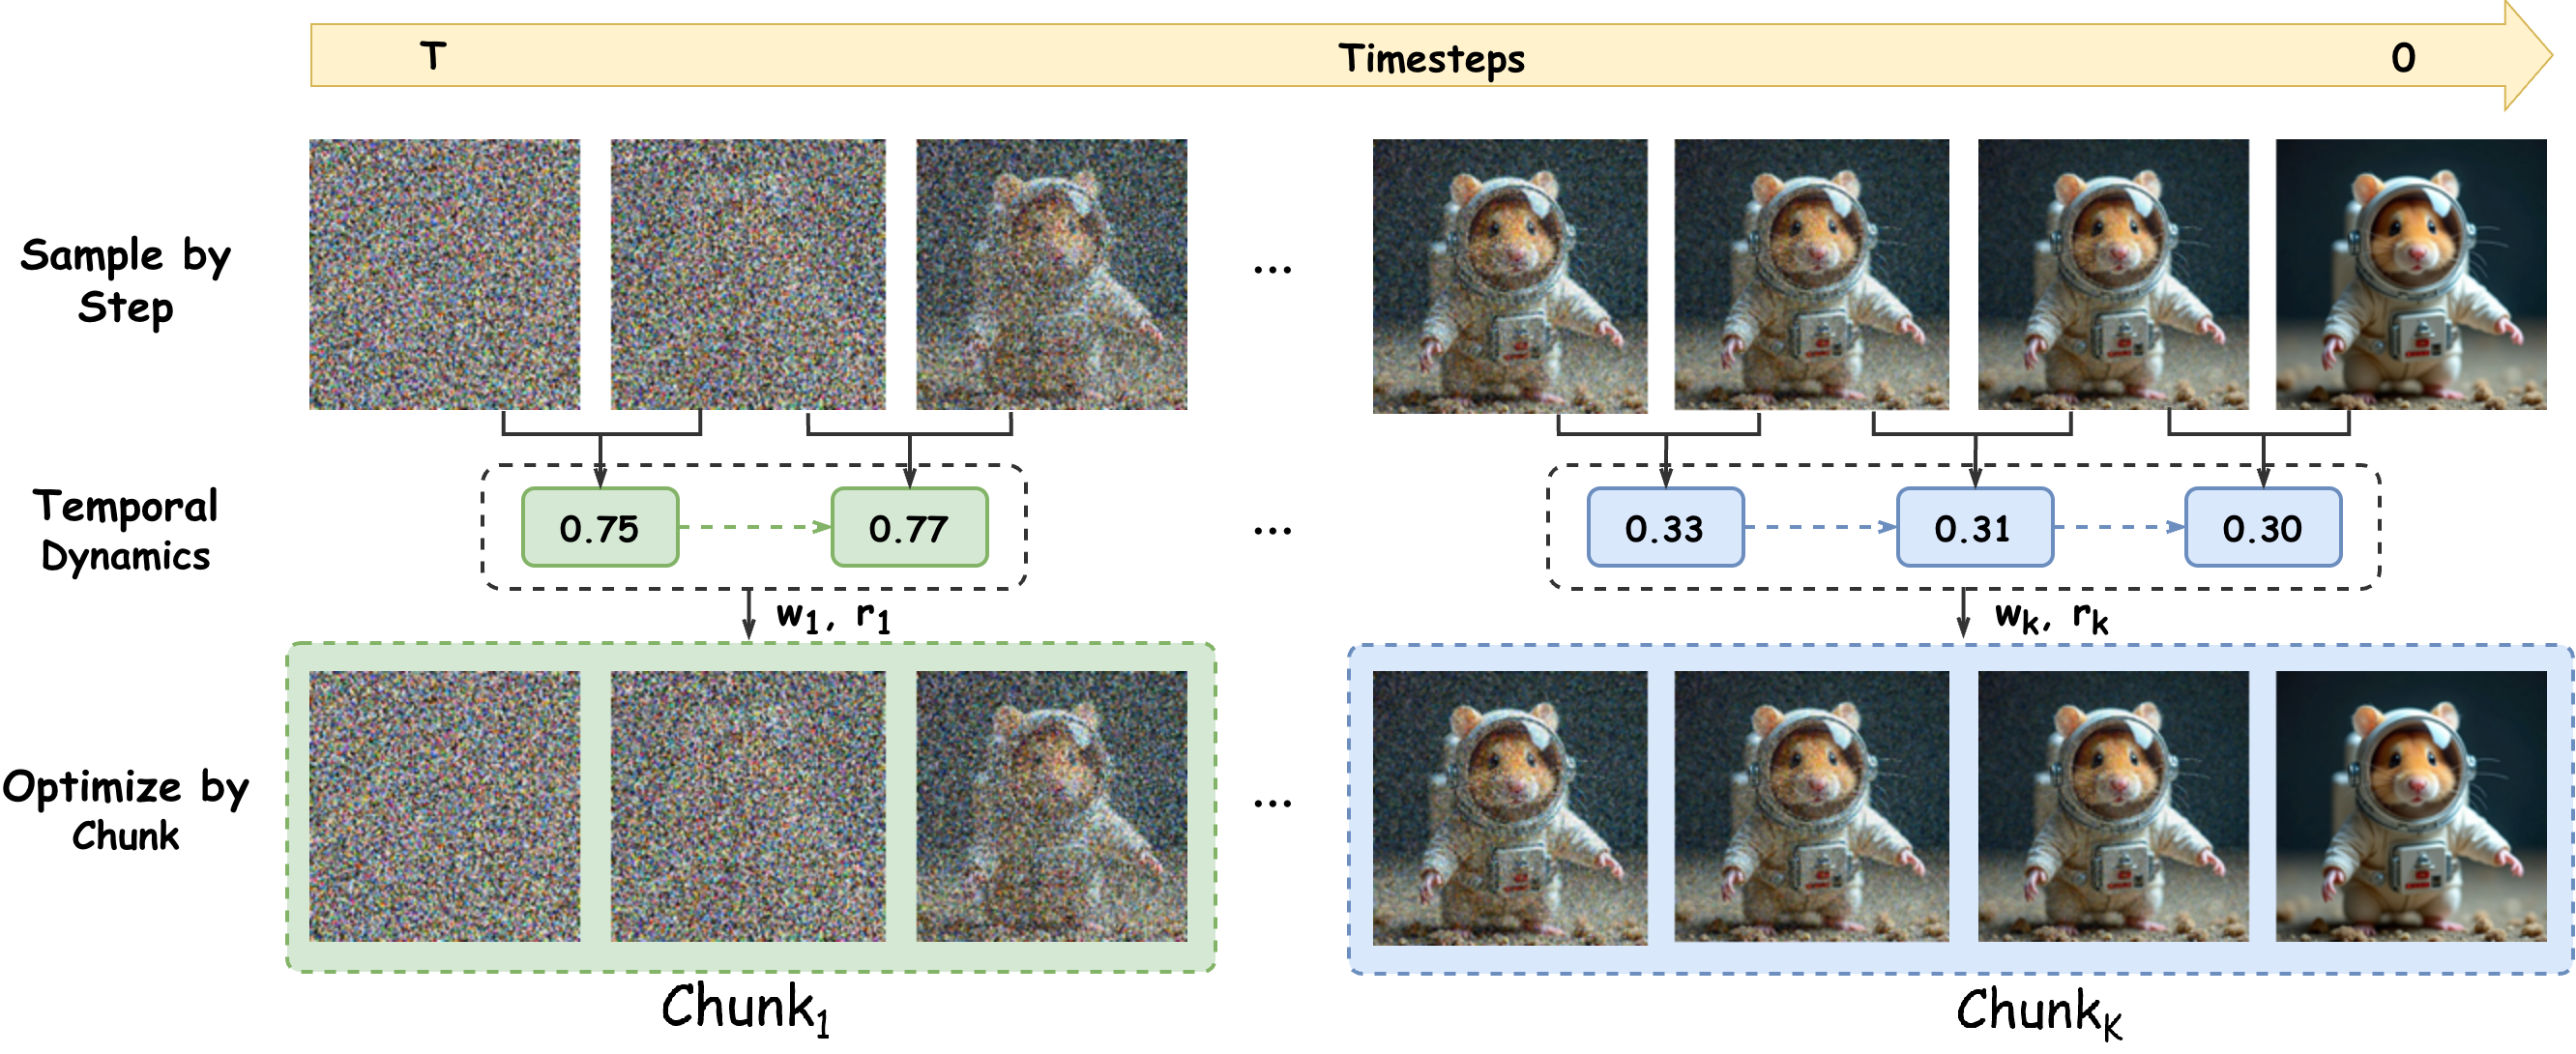
Principled RL for Flow Matching Emerges from the Chunk-level Policy Optimization
Yifu Luo*, Haoyuan Sun*, Xinhao Hu*, Penghui Du*, Keyu Fan, Bo Li, Sinan Du, Wan Xu, Zhiyu Chen, Bo Xia, Yongzhe Chang, Changqian Yu, Kun Gai, Tiantian Zhang, Xueqian Wang (* equal contribution)
Forty-Third International Conference on Machine Learning (ICML) 2026
Propose a chunk-level RL optimization for flow-matching text-to-image generation. We shift GRPO from the step-level to the chunk-level, aggregating consecutive steps into a coherent “chunk” to mitigate the sparse rewards bottleneck.
Principled RL for Flow Matching Emerges from the Chunk-level Policy Optimization
Yifu Luo*, Haoyuan Sun*, Xinhao Hu*, Penghui Du*, Keyu Fan, Bo Li, Sinan Du, Wan Xu, Zhiyu Chen, Bo Xia, Yongzhe Chang, Changqian Yu, Kun Gai, Tiantian Zhang, Xueqian Wang (* equal contribution)
Forty-Third International Conference on Machine Learning (ICML) 2026
Propose a chunk-level RL optimization for flow-matching text-to-image generation. We shift GRPO from the step-level to the chunk-level, aggregating consecutive steps into a coherent “chunk” to mitigate the sparse rewards bottleneck.
Reinforcement Learning Meets Masked Generative Models: Mask-GRPO for Text-to-Image Generation
Yifu Luo*, Xinhao Hu*, Keyu Fan*, Haoyuan Sun*, Zeyu Chen, Bo Xia, Tiantian Zhang, Yongzhe Chang, Xueqian Wang (* equal contribution)
Advances in Neural Information Processing Systems 38 (NeurIPS) 2025 13 citations
Propose the first GRPO approach for masked generative models in text-to-image generation. We redefine the transition probability tailored specifically for masked generative models, and explore several useful strategies to further enhance our method.
Reinforcement Learning Meets Masked Generative Models: Mask-GRPO for Text-to-Image Generation
Yifu Luo*, Xinhao Hu*, Keyu Fan*, Haoyuan Sun*, Zeyu Chen, Bo Xia, Tiantian Zhang, Yongzhe Chang, Xueqian Wang (* equal contribution)
Advances in Neural Information Processing Systems 38 (NeurIPS) 2025 13 citations
Propose the first GRPO approach for masked generative models in text-to-image generation. We redefine the transition probability tailored specifically for masked generative models, and explore several useful strategies to further enhance our method.